Journal of University of Chinese Academy of Sciences ›› 2026, Vol. 43 ›› Issue (5): 667-676.DOI: 10.7523/j.ucas.2024.072
• Electronics and Computer Science • Previous Articles Next Articles
Shixiang XIAO1, Wenzhen HUANG2, Jianbin JIAO1( )
Received:2023-12-04
Revised:2024-09-05
Online:2026-09-15
Contact:
Jianbin JIAO
CLC Number:
Shixiang XIAO, Wenzhen HUANG, Jianbin JIAO. Model-based exploration-learning joint optimization via uncertainty augmentation[J]. Journal of University of Chinese Academy of Sciences, 2026, 43(5): 667-676.
Add to citation manager EndNote|Ris|BibTeX
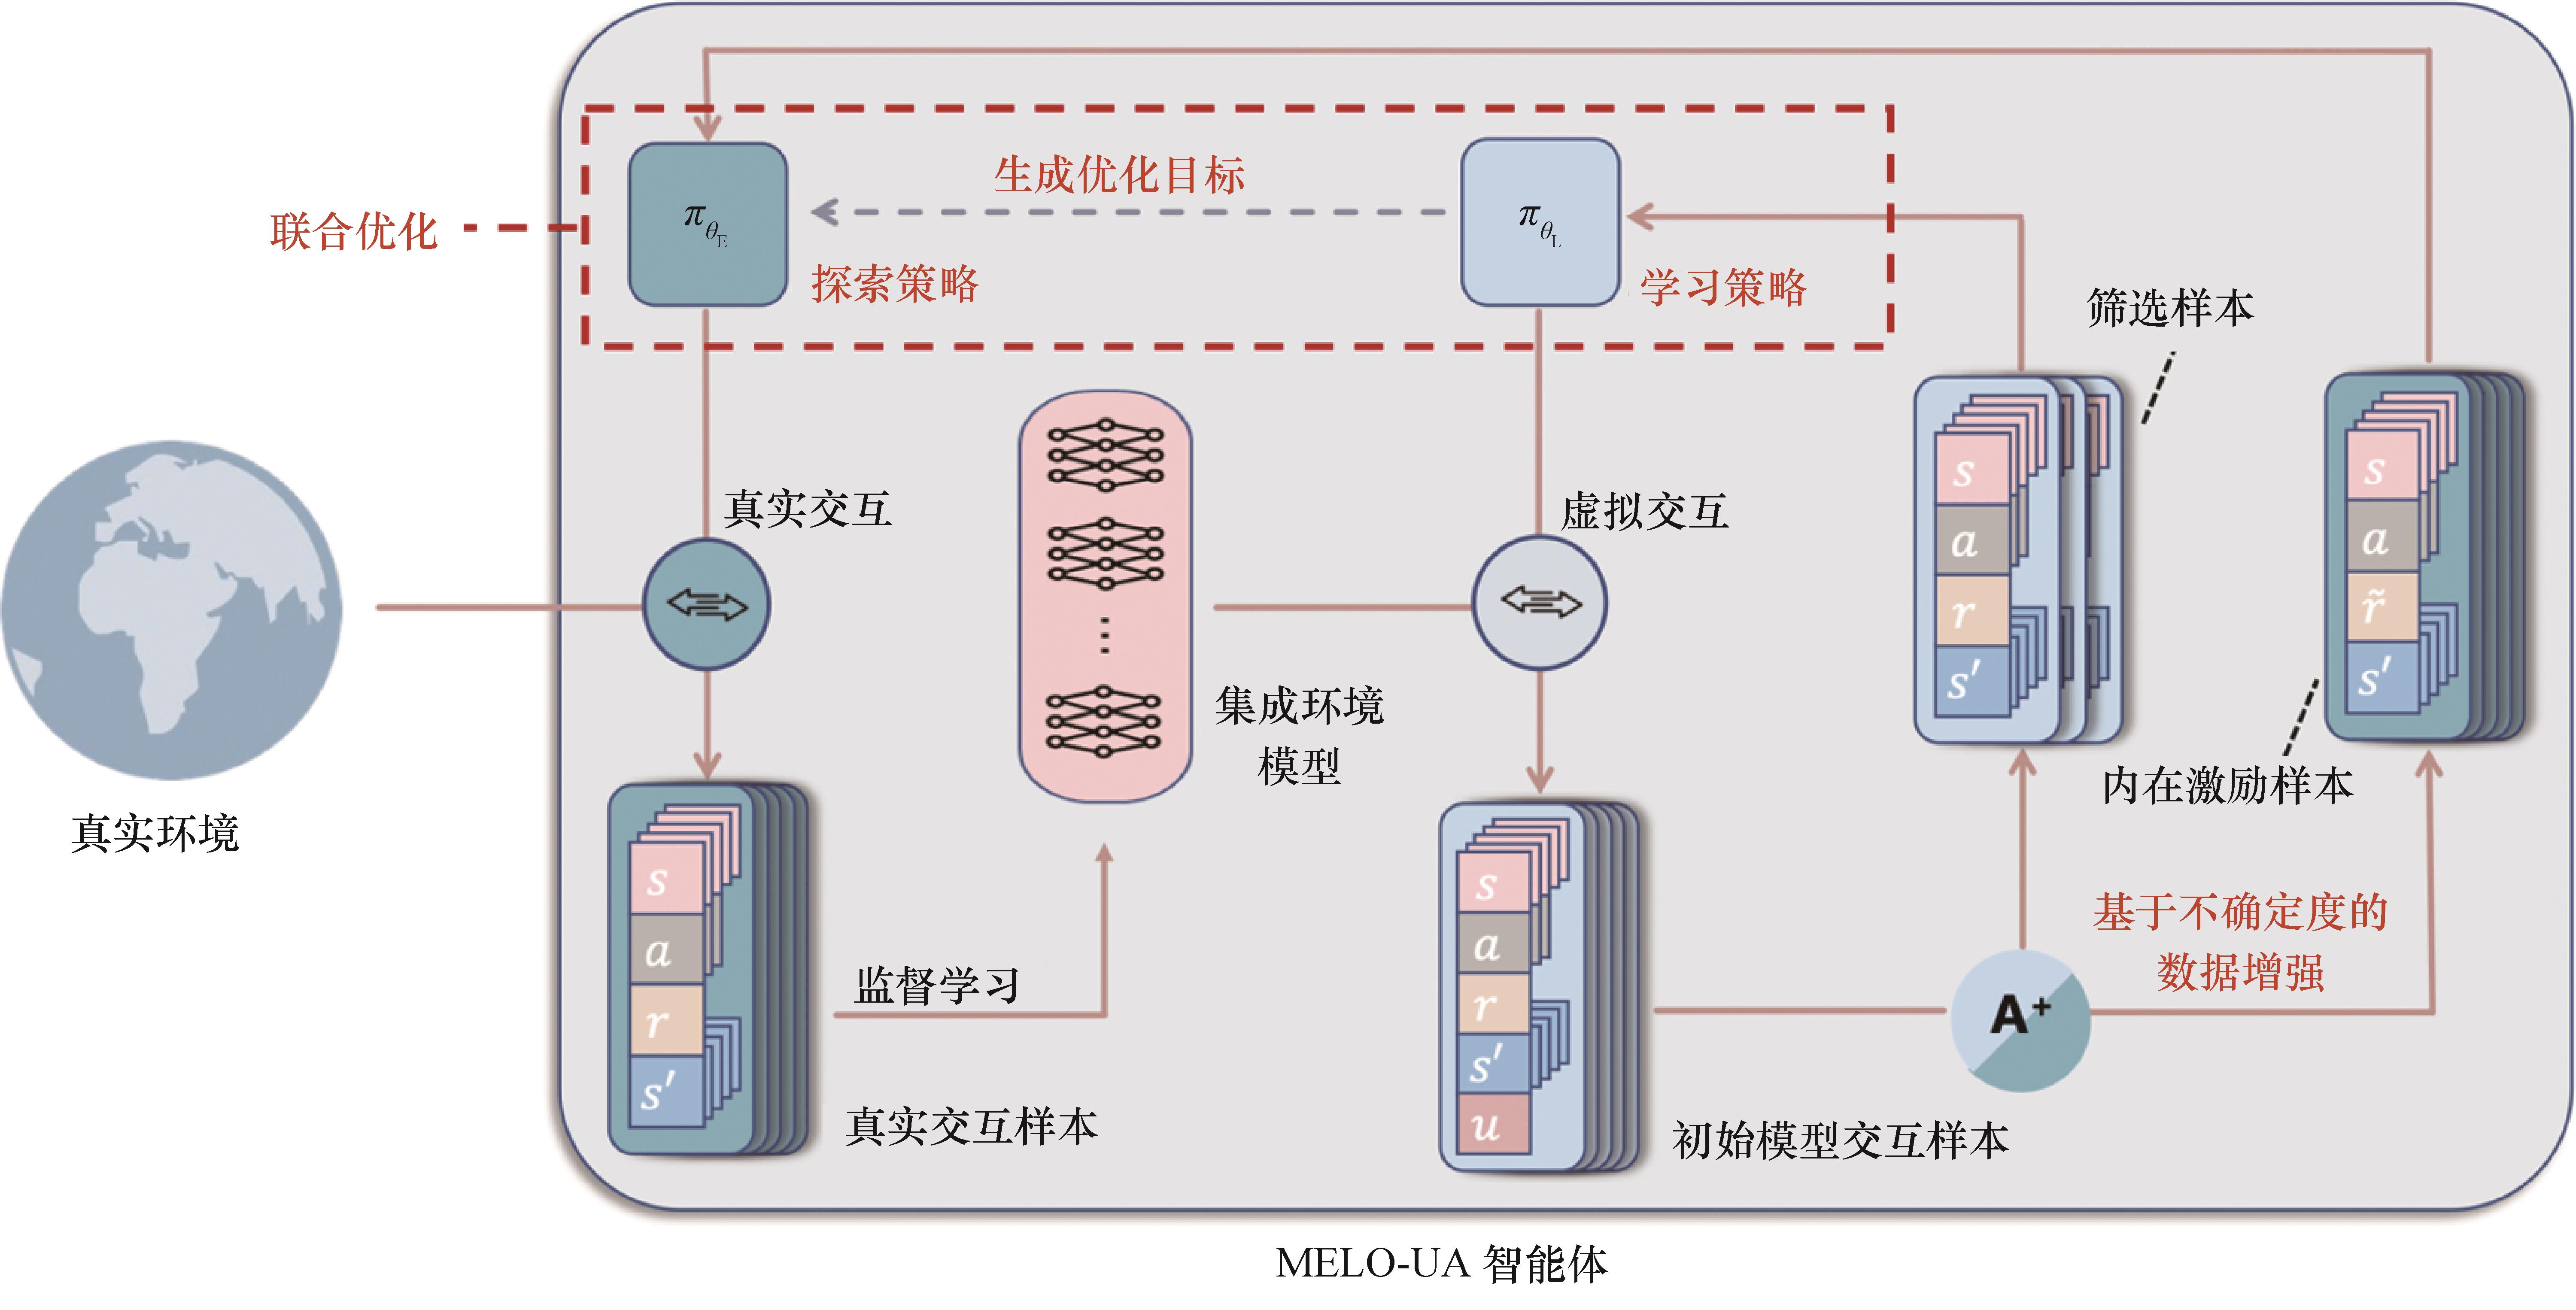
Fig.1 Model structure of MELO-UA
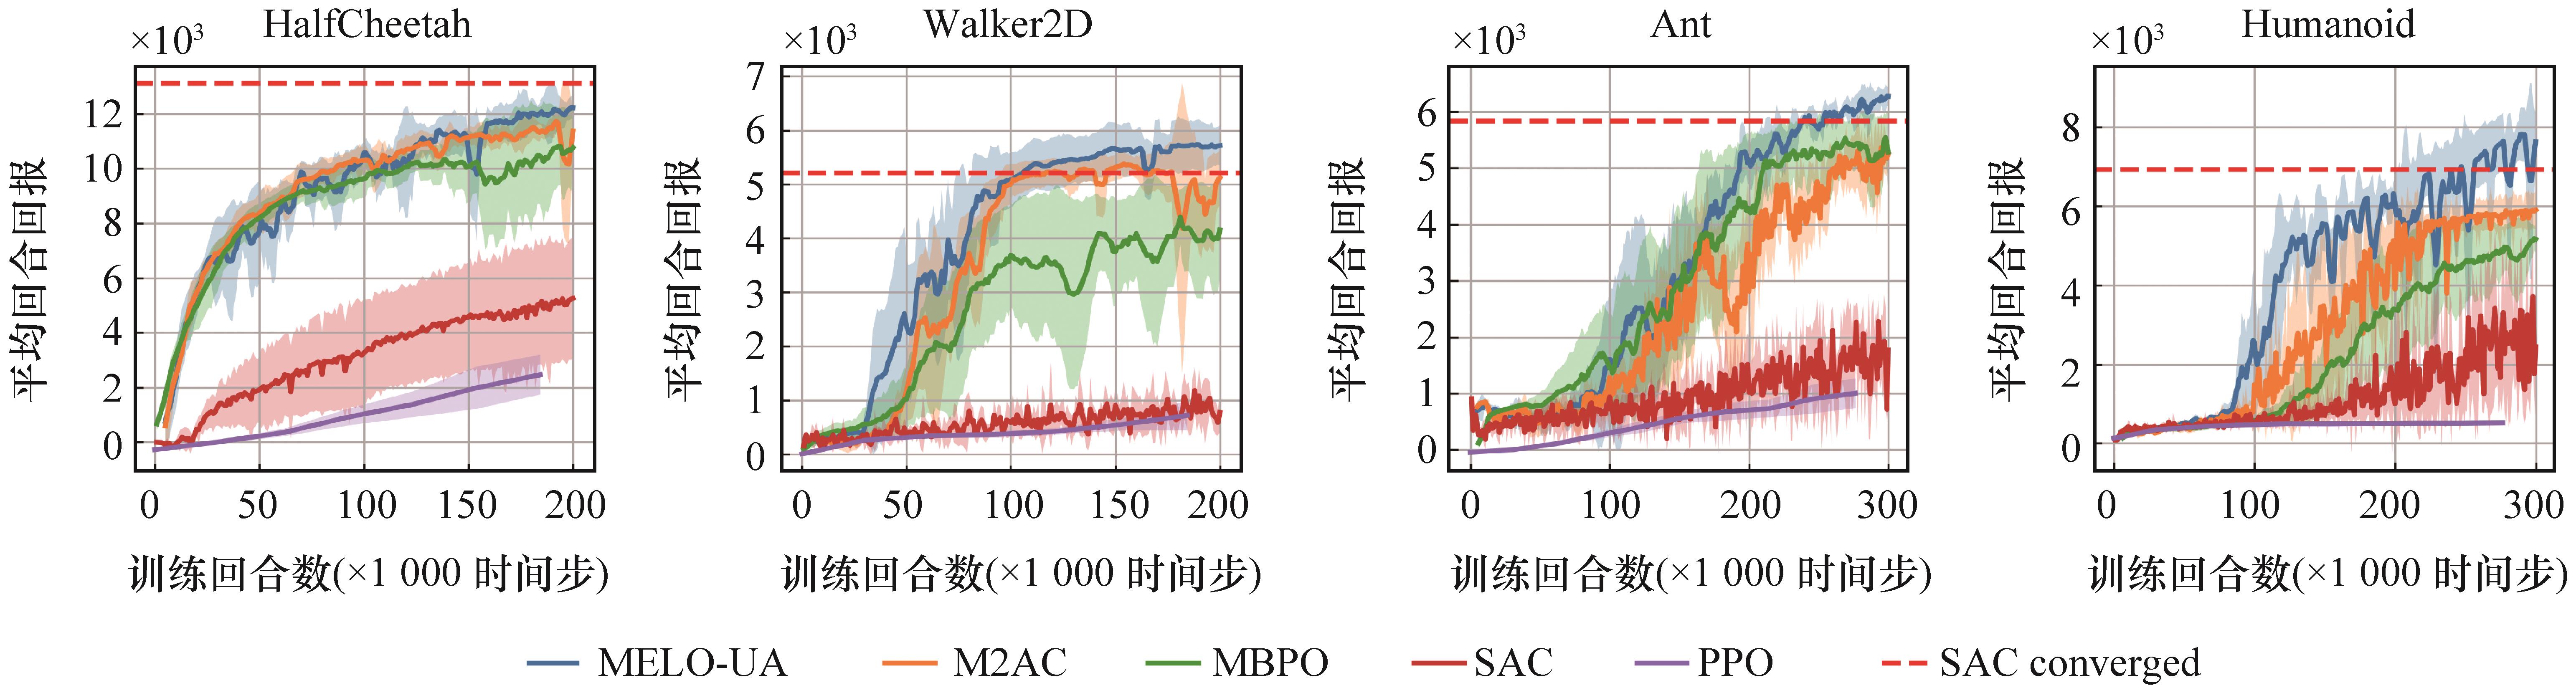
Fig.2 Performance of MELO-UA and baselines on MuJoCo
| 模型名称 | 说明 |
|---|---|
| MBPO | - |
| MBPO-B | 在MBPO上加入基于不确定度的奖励 |
| MBPO-P | 在MBPO上加入基于不确定度的约束 |
| MELO-UA | - |
| MELO-UA-I | 消去联合优化的MELO-UA |
| MELO-UA-s1 | 多步不确定度的前向视野为1 |
| MELO-UA-s5 | 多步不确定度的前向视野为5 |
Table 1 Algorithm information in ablation study
| 模型名称 | 说明 |
|---|---|
| MBPO | - |
| MBPO-B | 在MBPO上加入基于不确定度的奖励 |
| MBPO-P | 在MBPO上加入基于不确定度的约束 |
| MELO-UA | - |
| MELO-UA-I | 消去联合优化的MELO-UA |
| MELO-UA-s1 | 多步不确定度的前向视野为1 |
| MELO-UA-s5 | 多步不确定度的前向视野为5 |

Fig.3 Result of ablation study
| [1] | Schrittwieser J, Antonoglou I, Hubert T, et al. Mastering Atari, Go, chess and shogi by planning with a learned model[J]. Nature, 2020, 588(7839): 604-609. DOI: 10.1038/s41586-020-03051-4 . |
| [2] | Silver D, Schrittwieser J, Simonyan K, et al. Mastering the game of Go without human knowledge[J]. Nature, 2017, 550(7676): 354-359. DOI: 10.1038/nature24270 . |
| [3] | Schulman J, Wolski F, Dhariwal P, et al. Proximal policy optimization algorithms[EB/OL]. arXiv 2017:1707.06347. (2017-07-20)[2024-07-23]. . |
| [4] | Mnih V, Kavukcuoglu K, Silver D, et al. Human-level control through deep reinforcement learning[J]. Nature, 2015, 518(7540): 529-533. DOI: 10.1038/nature14236 . |
| [5] | Janner M, Fu J, Zhang M, et al. When to trust your model: model-based policy optimization[EB/OL]. arXiv 2019:1906.08253. (2019-06-19)[2024-07-23]. . |
| [6] | Nagabandi A, Kahn G, Fearing R S, et al. Neural network dynamics for model-based deep reinforcement learning with model-free fine-tuning[C]//2018 IEEE International Conference on Robotics and Automation (ICRA). Brisbane, QLD, Australia. IEEE, 2018: 7559-7566. DOI: 10.1109/ICRA.2018.8463189 . |
| [7] | Higuera J C G, Meger D, Dudek G. Synthesizing neural network controllers with probabilistic model-based reinforcement learning[C]//2018 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS). IEEE, 2018: 2538-2544. DOI: 10.1109/IROS.2018.8594018 . |
| [8] | Chua K, Calandra R, McAllister R, et al. Deep reinforcement learning in a handful of trials using probabilistic dynamics models[C]//Proceedings of the 32nd International Conference on Neural Information Processing Systems. December 3 - 8, 2018, Montréal, Canada. ACM, 2018: 4759-4770. DOI: 10.5555/3327345.3327385 . |
| [9] | Feinberg V, Wan A, Stoica I, et al. Model-based value estimation for efficient model-free reinforcement learning[EB/OL]. arXiv 2018:1803.00101. (2018-02-28)[2024-07-23]. . |
| [10] | Sutton R S. Integrated architectures for learning, planning, and reacting based on approximating dynamic programming[M]//Machine Learning Proceedings 1990. Amsterdam: Elsevier, 1990: 216-224. DOI: 10.1016/b978-1-55860-141-3.50030-4 . |
| [11] | Luo Y, Xu H, Li Y, et al. Algorithmic Framework for model-based deep reinforcement learning with theoretical guarantees[C/OL]//International Conference on Learning Representations. 2019. (2018-12-21)[2024-07-23]. . |
| [12] | Buckman J, Hafner D, Tucker G, et al. Sample-efficient reinforcement learning with stochastic ensemble value expansion[C]//Proceedings of the 32nd International Conference on Neural Information Processing Systems. December 3 - 8, 2018, Montréal, Canada. ACM, 2018: 8234-8244. DOI: 10.5555/3327757.3327916 . |
| [13] | Deisenroth M P, Rasmussen C E. PILCO: a model-based and data-efficient approach to policy search[C]//Proceedings of the 28th International Conference on International Conference on Machine Learning. 28 June 2011, Bellevue, Washington, USA. ACM, 2011: 465-472. DOI: 10.5555/3104482.3104541 . |
| [14] | Heess N, Wayne G, Silver D, et al. Learning continuous control policies by stochastic value gradients[EB/OL]. arXiv 2015:1510.09142. (2015-10-30)[2024-07-23]. . |
| [15] | Hafner D, Lillicrap T, Ba J, et al. Dream to control: Learning behaviors by latent imagination[EB/OL]. arXiv 2019:1912.01603. (2019-12-03)[2024-07-24]. . |
| [16] | Hafner D, Pasukonis J, Ba J, et al. Mastering diverse domains through world models[EB/OL]. arXiv 2023:2301.04104. (2023-01-10)[2024-07-23]. . |
| [17] | Hafner D, Lillicrap T, Fischer I, et al. Learning latent dynamics for planning from pixels[EB/OL]. arXiv 2018:1811.04551. (2018-11-12)[2024-07-23]. . |
| [18] | Kurutach T, Clavera I, Duan Y, et al. Model-ensemble trust-region policy optimization[EB/OL]. arXiv 2018:1802.10592. (2018-02-28)[2024-07-23]. . |
| [19] | He W, Jiang Z. A Comprehensive Survey on Uncertainty Quantification for Deep Learning[EB/OL]. arXiv 2023:2302.13425. (2023-02-26)[2024-07-23]. . |
| [20] | Psaros A F, Meng X H, Zou Z R, et al. Uncertainty quantification in scientific machine learning: methods, metrics, and comparisons[J]. Journal of Computational Physics, 2023, 477: 111902. DOI: 10.1016/j.jcp.2022.111902 . |
| [21] | Lakshminarayanan B, Pritzel A, Blundell C. Simple and scalable predictive uncertainty estimation using deep Ensembles[EB/OL]. arXiv 2016:1612.01474. (2016-12-05)[2024-07-23]. . |
| [22] | Wang Z, Jusup M, Shi L, et al. Exploiting a cognitive bias promotes cooperation in social dilemma experiments[J]. Nature Communications, 2018, 9(1): 2954. DOI: 10.1038/s41467-018-05259-5 . |
| [23] | Lu C, Ball P, Parker-Holder J, et al. Revisiting design choices in offline model-based reinforcement learning[EB/OL]. arXiv 2021:2110.04135. (2021-10-08)[2024-07-23]. . |
| [24] | Pan F, He J, Tu D, et al. Trust the model when it is confident: masked model-based actor-critic[EB/OL]. arXiv 2020:2020.04893. (2020-10-10)[2024-07-23]. . |
| [25] | Yu T H, Thomas G, Yu L T, et al. MOPO: model-based offline policy optimization[EB/OL]. arXiv 2020:2005.13239. (2020-05-27)[2024-07-23]. . |
| [26] | Bechtle S, Lin Y X, Rai A, et al. Curious iLQR: resolving uncertainty in model-based RL[EB/OL]. arXiv 2019:1904.06786. (2019-04-15)[2024-07-23]. . |
| [27] | Hao J Y, Yang T P, Tang H Y, et al. Exploration in deep reinforcement learning: from single-agent to multiagent domain[J]. IEEE Transactions on Neural Networks and Learning Systems, 2023. DOI: 10.1109/TNNLS.2023.3236361 . |
| [28] | Abbasi-Yadkori Y, Pl D, Szepesvári C. Improved algorithms for linear stochastic bandits[C]//Proceedings of the 24th International Conference on Neural Information Processing Systems. December 12 - 15, 2011, Granada, Spain. ACM, 2011: 2312-2320. DOI: 10.5555/2986459.2986717&widgetKey=ux3-publicationContent-widget_f69d88a8-b404 -4aae-83 a9-9 acea 4426d78_1498 _en. |
| [29] | Bai C J, Wang L X, Han L, et al. Principled exploration via optimistic bootstrapping and backward induction[EB/OL]. arXiv 2021:2105.06022. (2021-05-13)[2024-07-23]. . |
| [30] | Zheng Y, Liu Y, Xie X F, et al. Automatic web testing using curiosity-driven reinforcement learning[C]//2021 IEEE/ACM 43rd International Conference on Software Engineering (ICSE). Madrid, ES. IEEE, 2021: 423-435. DOI: 10.1109/ICSE43902.2021.00048 . |
| [31] | Ciosek K, Vuong Q, Loftin R, et al. Better exploration with optimistic actor-critic[EB/OL]. arXiv 2019:1910.12807. (2019-10-28)[2024-07-23]. . |
| [32] | Haarnoja T, Zhou A, Abbeel P, et al. Soft actor-critic: off-policy maximum entropy deep reinforcement learning with a stochastic actor[EB/OL]. arXiv 2018:1801.01290. (2018-01-04)[2024-07-23]. . |
| [33] | Burda Y, Edwards H, Storkey A, et al. Exploration by random network distillation[EB/OL]. arXiv 2018:1810.12894. (2018-10-30)[2024-07-23]. . |
| [34] | Liu J Y, Wang Z, Zheng Y, et al. OVD-explorer: optimism should not be the sole pursuit of exploration in noisy environments[J]. Proceedings of the AAAI Conference on Artificial Intelligence, 2024, 38(12): 13954-13962. DOI: 10.1609/aaai.v38i12.29303 . |
| [35] | Bai C J, Wang L X, Han L, et al. Dynamic bottleneck for robust self-supervised exploration[EB/OL]. arXiv 2021:2110.10735. (2021-10-20)[2024-07-23]. . |
| [36] | Oudeyer P Y, Kaplan F, Hafner V V. Intrinsic motivation systems for autonomous mental development[J]. IEEE Transactions on Evolutionary Computation, 2007, 11(2): 265-286. DOI: 10.1109/TEVC.2006.890271 . |
| [37] | Pathak D, Agrawal P, Efros A A, et al. Curiosity-driven exploration by self-supervised prediction[C/OL]//2017 IEEE Conference on Computer Vision and Pattern Recognition Workshops (CVPRW). 2017: 488-489. DOI:10.1109/CVPRW.2017.70 . |
| [38] | Pathak D, Gandhi D, Gupta A. Self-supervised exploration via disagreement[EB/OL]. arXiv 2019:1906.04161. (2019-01-10)[2024-07-23]. . |
| [39] | Yuan Y F, Hao J Y, Ni F, et al. EUCLID: towards efficient unsupervised reinforcement learning with multi-choice dynamics model[EB/OL]. arXiv 2022:2210.00498. (2022-10-02)[2024-07-23]. . |
| [40] | Haarnoja T, Tang H R, Abbeel P, et al. Reinforcement learning with deep energy-based policies[EB/OL]. arXiv 2017:1702.08165. (2017-02-27)[2024-07-23]. . |
| [41] | Pineda L, Amos B, Zhang A, et al. MBRL-lib: a modular library for model-based reinforcement learning[EB/OL]. arXiv 2021:2104.10159. (2021-04-20)[2024-07-23]. . |
| [1] | Zhonghui MA, Zhenzhen CUI, Dongchuan YAN, Bingjie LIU, Yi WAN, Zhiqiang WANG, Chenglong ZHANG. Long time series cross radiometric calibration of HJ-1A/CCD1 [J]. Journal of University of Chinese Academy of Sciences, 2026, 43(1): 104-114. |
| [2] | LI Xueyuan, HAN Congying. Solving quadratic assignment problem based on actor-critic framework [J]. Journal of University of Chinese Academy of Sciences, 2024, 41(2): 275-284. |
| [3] | YANG Guangkai, CHEN Hao, ZHANG Mingyi, YIN Qiyue, HUANG Kaiqi. Uncertainty-based credit assignment for cooperative multi-agent reinforcement learning [J]. Journal of University of Chinese Academy of Sciences, 2024, 41(2): 231-240. |
| [4] | CHEN Hao, YANG Likun, YIN Qiyue, HUANG Kaiqi. Local observation reconstruction for Ad-Hoc cooperation [J]. Journal of University of Chinese Academy of Sciences, 2024, 41(1): 117-126. |
| [5] | ZHANG Huaming, LI Qiang. Downlink power allocation scheme for LEO satellites based on deep reinforcement learning [J]. Journal of University of Chinese Academy of Sciences, 2022, 39(4): 543-550. |
| [6] | JIN Xiaohan, YAN Yan, ZHANG Baoxian. Energy efficient opportunistic routing for wireless multihop networks: a deep reinforcement learning approach [J]. Journal of University of Chinese Academy of Sciences, 2022, 39(3): 410-420. |
| [7] | WANG Shuang, LI Junli, WANG Hui, MENG Fangxia, QIAO Congfeng. Experimental test of the uncertainty relations for mixed states [J]. Journal of University of Chinese Academy of Sciences, 2021, 38(6): 735-740. |
| [8] | SONG Qiucheng, QIAO Congfeng. Uncertainty equalities and uncertainty relation in weak measurement [J]. , 2016, 33(1): 37-41. |
| [9] | YANG Xiaofang, WANG Mingyu, WANG Liya, ZHAO Jianhui. Investigation of key controlling factors and numerical simulation uncertainty of the groundwater level companying with Yongding river ecological restoration [J]. , 2015, 32(2): 192-199. |
| [10] | Tang Su-Fang, Niu Peng-Cheng. Several new versions of Hardy's uncertainty principles on harmonic NA groups [J]. , 2009, 26(1): 1-8. |
| [11] | XU Chong-Gang, HU Yuan-Man, CHANG Yu, LI Xiu-Zhen, BU Ren-Cang, HE Hong-Shi. Geostatistical Modeling of Spatial Uncertainty in a Spatially Explicit Forest Landscape Model Simulation [J]. , 2005, 22(4): 436-446. |
| [12] | Zhu Liang, Jiang Changsheng, Fu Xiaorong. Design of Robust Decentralized Controller for Uncertain Large- Scale Interconnected Systems with Input Delay Using Reduction Method [J]. , 2005, 22(1): 38-45. |
| Viewed | ||||||
|
Full text |
|
|||||
|
Abstract |
|
|||||
Copyright © Journal of University of Chinese Academy of Sciences
Support by Beijing Magtech Co.ltd support@magtech.com.cn

